Amazon Bedrock AI Agents

Amazon Bedrock AI Agent Use Cases

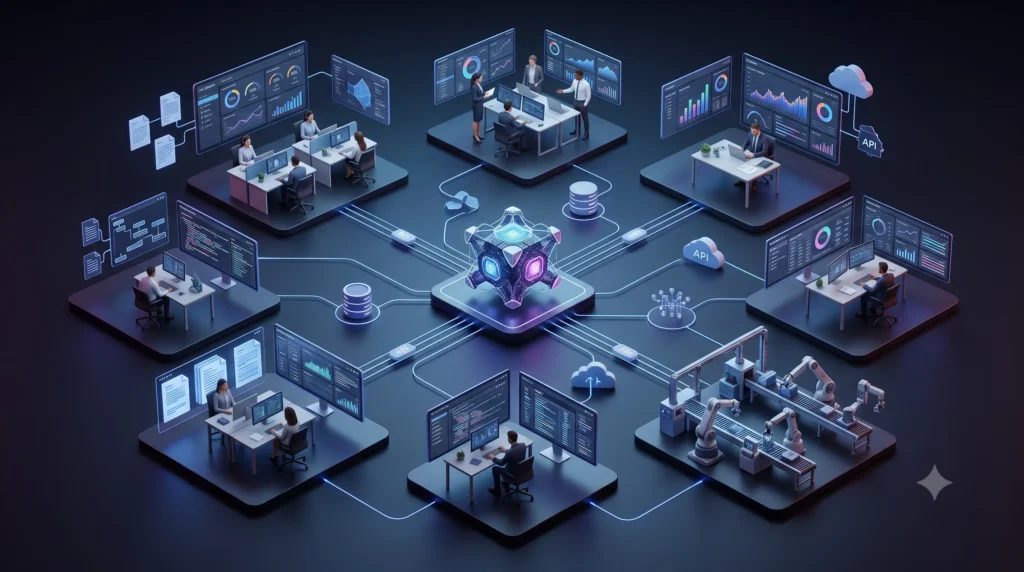
Top Amazon Bedrock AI Agent Use Cases for Enterprises: 15 Generative AI Solutions We Build 🕑 8 min read | 📂 Enterprise AI | 🎯 For CTOs, HR Leaders, L&D Heads Amazon Bedrock AI Agent Use Cases are expanding rapidly as enterprises move beyond basic chatbots toward AI systems that can understand business requirements, access enterprise data, use tools, interact with applications and execute multi-step workflows. For enterprises, the opportunity is much bigger than asking an AI model to generate text. Generative AI can be applied across customer service, sales, procurement, finance, document processing, manufacturing, employee support and enterprise knowledge management. At Logassa LLC, we design and build Amazon Bedrock AI solutions, enterprise AI agents, RAG applications, AI copilots and intelligent automation systems around real business requirements. Our document intelligence capabilities also include OCR and vision-based document processing, helping businesses extract useful information from documents and connect it to downstream workflows. Amazon Bedrock provides access to foundation models and capabilities for building generative AI applications, while Amazon Bedrock AgentCore provides managed capabilities designed to help organizations build, deploy and operate AI agents securely at scale. What Can You Build With Amazon Bedrock? Amazon Bedrock can be used as a foundation for a wide range of enterprise AI applications. Some of the most valuable use cases include: 1. AI Customer Service Agents 2. AI Sales Agents 3. AI Procurement Agents 4. AI Finance Agents 5. AI HR Assistants 6. AI Manufacturing Copilots 7. AI Maintenance Agents 8. AI Document Intelligence 9. AI RFP & Proposal Automation 10. AI Email Agents 11. AI HR Agent 12. AI Research Agent 13. Multi-Agent Enterprise Systems 14. AI Workflow Automation 15. Enterprise RAG Applications Let’s look at how these solutions can work in real business environments. The 15 Use Cases in Detail: 15 Enterprise Use Cases We Build on Amazon Bedrock 1. AI Customer Service Agent Customer support is one of the strongest use cases for enterprise AI agents. A traditional chatbot may answer questions from a predefined knowledge base – an AI agent can go much further. It can understand the customer’s request, retrieve relevant information, access business systems and take appropriate actions. “Where is my order and when will it arrive?” Understand request   →   Identify customer   →   Access CRM / order system   →   Retrieve order info   →   Check delivery status   →   Respond   →   Escalate if required AgentCore’s documented use cases include customer service agents that securely access CRM data, support tickets and knowledge bases during customer interactions. We can build: – Website AI customer support – Customer portal assistants –  AI ticketing agents – Product support agents – Warranty assistants – Technical troubleshooting agents – Multilingual customer support 2. AI Sales Agent Sales teams spend a significant amount of time on repetitive activities. An AI Sales Agent can assist with lead qualification, prospect research, lead scoring, CRM updates, customer profiling, email generation, follow-ups, meeting preparation, proposal generation and sales reporting. New lead   →   AI sales agent   →   Company research   →   Requirement analysis   →   Lead scoring   →   CRM update   →   Personalized email   →   Follow-up Instead of replacing salespeople, the AI agent becomes a digital sales assistant that handles repetitive work while sales teams focus on relationships and closing deals. 3. AI Procurement Agent Procurement departments deal with large numbers of suppliers, quotations, purchase requests and purchase orders. An AI Procurement Agent can automate significant parts of this process. Purchase requirement   →   AI procurement agent   →   Check inventory   →   Find approved suppliers   →   Request quotations   →   Compare prices   →   Analyze delivery terms   →   Recommendation   →   Manager approval   →   Purchase order Potential applications: – RFQ automation –  Supplier comparison – Vendor analysis – Purchase recommendation – Purchase-order preparation – Procurement email automation – Supplier communication This is particularly relevant for manufacturing and large enterprises. 3. AI Procurement Agent Procurement departments deal with large numbers of suppliers, quotations, purchase requests and purchase orders. An AI Procurement Agent can automate significant parts of this process. Purchase requirement   →   AI procurement agent   →   Check inventory   →   Find approved suppliers   →   Request quotations   →   Compare prices   →   Analyze delivery terms   →   Recommendation   →   Manager approval   →   Purchase order Potential applications: – RFQ automation –  Supplier comparison – Vendor analysis – Purchase recommendation – Purchase-order preparation – Procurement email automation – Supplier communication This is particularly relevant for manufacturing and large enterprises. 4. AI Finance Agent Finance departments process enormous volumes of structured and unstructured information. An AI Finance Agent can assist with invoice processing, purchase-order matching, expense processing, vendor analysis, financial document analysis, payment workflows, financial reporting and exception detection. Vendor invoice   →   Document AI   →   Information extraction   →   Amazon Bedrock   →   PO / GRN matching   →   Validation   →   Exception detection   →   Approval   →   ERP The AI can identify unusual or incomplete transactions and route them to the appropriate human reviewer. 5. Enterprise AI Knowledge Assistant Most enterprises have valuable knowledge scattered across PDFs, SOPs, manuals, SharePoint, Google Drive, Confluence, internal documentation, engineering documents, policies and reports. Employees often spend hours searching for information. An enterprise knowledge assistant can provide a natural-language interface to this information. “What is the maintenance procedure for Machine X?” The system retrieves the relevant documents and generates a grounded response. Amazon Bedrock Knowledge Bases supports RAG workflows that retrieve relevant enterprise information and use it to improve generated responses and can return source citations so users can verify the underlying information. 6. AI Manufacturing Co-pilot Manufacturing organizations generate massive amounts of production data, machine data, quality information, maintenance records, SOPs, engineering documentation, shift reports and inventory

Amazon Bedrock AI Agent Use Cases Read More »
AI GCC in India

AI GCC: Companies Building AI Capability Centres in India

AI GCC: Why Global Companies Are Building AI Capability Centres in India? 🕑 4 min read | 📂 Enterprise AI | 🎯 For CTOs, HR Leaders, L&D Heads AI GCC is quickly becoming more than another technology buzzword. As artificial intelligence moves from experimentation into real business operations, global companies are rethinking where and how they build their AI capabilities. For many enterprises, the answer increasingly points toward India. India’s Global Capability Centres (GCCs) have already moved far beyond their traditional role as offshore support and cost-optimization units. They are now involved in product engineering, research and development, data science, cybersecurity, cloud, automation and increasingly, artificial intelligence. Current industry estimates put India’s GCC ecosystem at more than 2,100 centres employing around 2.36 million professionals and generating nearly $100 billion in annual revenue. At the same time, AI adoption is accelerating. EY’s 2025 GCC Pulse Survey found that 58% of India-based GCCs were already investing in Agentic AI, while another 29% planned to scale their investments within the following year. This convergence is creating a new model: the AI-focused Global Capability Centre. What Is an AI GCC? So, what is AI GCC in practical terms? An AI GCC is a Global Capability Centre designed or expanded specifically to build, deploy and scale artificial intelligence capabilities for a company’s global operations. Instead of focusing primarily on support functions, an AI-focused GCC can bring together AI engineers, data scientists, ML engineers, software developers, domain experts, product teams and automation specialists. The AI GCC full form can therefore be understood in the context of an AI-focused Global Capability Centre. The exact structure varies from company to company. One organisation may use its centre for AI research and model development, while another may focus on enterprise automation, computer vision, intelligent document processing, data platforms, AI agents or AI-enabled products. The common thread is ownership. A modern GCC is increasingly expected to create intellectual property, solve complex business problems and contribute directly to global product and technology strategies – not simply execute instructions from headquarters. Why Are Global Companies Building AI Capability Centres in India? The reasons go beyond lower operating costs. 1. Access to a Large Technology Talent Pool India has built one of the world’s largest technology talent ecosystems. This gives global enterprises access to engineers and specialists across software development, data engineering, machine learning, cloud computing, cybersecurity and AI. More importantly, the nature of demand is changing. Companies are no longer looking only for large engineering teams. They are looking for people who can work across disciplines – AI, software, data, product and business operations. This is one reason India’s GCC ecosystem is shifting from a headcount-driven model toward a capability-driven model. PwC’s recent analysis describes Indian GCCs as increasingly important platforms for AI research, advanced analytics, product engineering and enterprise transformation. 2. AI Development Requires More Than Buying an AI Model Businesses quickly discover that implementing AI is not simply a matter of subscribing to an API. An enterprise AI system needs data pipelines, model integration, application development, security, monitoring, governance and domain-specific workflows. That is where an AI GCC solution can become strategically valuable. A dedicated team can work on the entire AI lifecycle – from identifying use cases and preparing data to developing models, integrating AI into existing systems and continuously improving production deployments. For global companies, having these capabilities within a dedicated centre can create tighter coordination between engineering, business teams and AI initiatives. 3. India Is Moving From Execution to Ownership The biggest change in the GCC story is arguably this shift from execution to ownership. Earlier, a company might establish a centre in India to manage application maintenance, finance operations, customer support or other shared services. Today, Indian GCCs are increasingly involved in product development, R&D, advanced analytics, AI and global decision-making. NASSCOM‘s reporting on India’s GCC ecosystem highlights this evolution, noting that many centres are now taking ownership of end-to-end product lifecycles and high-value technology functions. That makes an AI capability centre fundamentally different from a traditional outsourcing model. The question is no longer, “How much work can we move to India?” It is becoming, “What strategic technology capabilities can we build in India?” The Rise of Agentic AI GCC Models Generative AI was the first major wave. The next one is increasingly agentic AI. Traditional enterprise software generally waits for users to initiate actions. AI agents can potentially reason through tasks, interact with systems, make decisions within defined boundaries and execute multi-step workflows. This is particularly relevant to GCCs because many of them already sit at the intersection of technology, business processes and enterprise data. EY’s 2025 research found that 58% of India-based GCCs were investing in Agentic AI, while 29% planned to scale investment over the following year. An agentic AI GCC could therefore become a central environment for building and testing AI agents for functions such as: The important point is that agentic AI is not valuable simply because it is autonomous. Its value comes from connecting intelligence with real business workflows. What Does an AI GCC Actually Build? The scope of an AI capability centre can be surprisingly broad. Depending on the organisation, an AI GCC service model can include: [1] AI and Machine Learning Teams can develop, fine-tune, evaluate and deploy machine learning models for specific business requirements. [2] Generative AI GCC teams can build enterprise applications around large language models, retrieval-augmented generation, private knowledge bases and AI-powered assistants. [3] AI Agents and Automation AI agents can be integrated with enterprise applications to automate repetitive or multi-step processes. [4] Computer Vision Manufacturing, logistics, healthcare, retail and other industries can use computer vision for inspection, detection, monitoring and visual analytics. [5] Intelligent Document Processing Documents remain one of the largest sources of unstructured business information. AI systems combining OCR, document understanding and machine learning can turn invoices, engineering documents, forms and reports into structured information. This is an area where AI India Innovations has practical experience. The company’s Computer Vision capabilities

AI GCC: Companies Building AI Capability Centres in India Read More »

AI Training for Companies workshop for US enterprise teams

AI Training for Companies USA

AI Training for Companies USA: Driving Enterprise Growth 🕑 6 min read | 📂 Enterprise AI | 🎯 For CTOs, HR Leaders, L&D Heads AI Training for Companies is no longer optional for US enterprises aiming to stay competitive. Artificial Intelligence has moved from experimentation to execution. However, most organizations still struggle with one critical gap – workforce readiness. At Logassa LLC, Austin, Texas, we help enterprises transform AI investments into measurable ROI through structured, compliance-ready AI training programs built for scale. The Enterprise Problem: AI Tools Exist, ROI Does Not Across the United States, companies are investing heavily in AI platforms for automation, analytics, marketing & engagement. Yet many fail to unlock full value. Common enterprise challenges include: – Employees unsure which AI tools to use – Misconception that AI is too technical – Fear of job displacement – Lack of structured governance – No measurable ROI framework Without proper AI Training for Companies, AI adoption becomes fragmented and underutilized. Practical AI Implementation Across Departments AI Training for Companies Across Enterprise Teams AI adoption must extend beyond IT. Logassa trains: – Marketing & HR Teams (AI-Driven Campaigns & Analytics) – Finance & Sales Teams (Predictive Insights, AI-Powered CRM & Automation) – Operations Leaders (Process Automation & Efficiency) – Executive Management (AI Strategy & Governance) Every session focuses on practical execution within real job functions. Eliminating the Fear: AI Enhances Human Performance One question dominates enterprise conversations: “Will AI replace jobs?” Through structured AI Training for Companies, teams quickly understand a critical truth: AI enhances performance. It does not replace expertise. Employees learn to: – Automate repetitive workflows – Improve data-driven decisions – Reduce manual processing time – Focus on strategic initiatives By the end of training, hesitation transforms into an innovative mindset. Measurable ROI from AI Training for Companies Organizations that implement structured AI Training for Companies experience measurable gains: ✔ Faster task execution & Reduced operational costs ✔ Improved research accuracy & Higher content quality ✔ Stronger cross-team collaboration ✔ Increased automation adoption Many enterprises report saving multiple hours per employee per week. At scale, this translates into significant operational ROI. Built for Enterprise Compliance & Scalability In the US market, compliance is non-negotiable. Logassa ensures that AI Training for Companies program aligns: HIPAA (Healthcare AI usage) SOC 2 (Security & governance controls) Data privacy best practices Responsible AI frameworks Logassa’s AI Training for Companies programs are designed for: Multi-location enterprises Hybrid and remote teams Enterprise-grade security environments Localite training for best availability AI adoption without compliance creates risk. AI training with governance creates competitive advantage. Why Do US Enterprises Choose Logassa? Companies partner with Logassa because we focus on: – Performance-driven AI integration with enterprise-grade security standards – Scalable workforce transformation – Automation-first thinking & ROI frameworks We do not just train teams on tools. We help enterprises build AI-ready cultures. The Future of Enterprise Growth Is AI-Enabled Artificial Intelligence is redefining business operations across the United States. However, competitive advantage does not come from owning AI platforms. It comes from empowering teams to use them effectively. AI Training for Companies bridges the gap between technology investment and business transformation. Ready to Scale with AI? 📈 If your organization is preparing for enterprise AI adoption, compliance alignment and measurable ROI, Logassa can help. Empower your workforce. Strengthen governance. Accelerate automation.

AI Training for Companies USA Read More »

Production RAG architecture

Production RAG Architecture: Moving Beyond Prototypes

Moving Beyond the Prototype: The Production RAG Architecture ⏱ 8–9 min read | 🏥 AI Innovation | 🎯 For Leaders, Decision Makers & Professionals Executive Summary: Production RAG architecture Production RAG architecture is the most Retrieval-Augmented Generation (RAG) demonstrations fail when moved into production environments. The common prototype stack — Vector Database + LLM — appears effective during small-scale experiments but quickly breaks under real-world usage.   Production RAG systems require three architectural foundations: – Disciplined data preparation through structured chunking and metadata – Retrieval precision using hybrid search and cross-encoder reranking – Generation guardrails including citations, refusal behavior, and context control   Once implemented, improvements must be validated through structured evaluation frameworks such as RAGAS and TruLens. Production RAG architecture is therefore a retrieval engineering problem, not simply a prompt engineering task. The Production RAG Architecture Wall: Why Most Prototypes Fail? Production RAG architecture prototypes succeed primarily because conditions are artificially favorable. Typical demos operate with: – small datasets – predictable questions – limited evaluation standards However, once deployed to real users, several failure modes quickly appear.   Semantic Drift Users phrase questions differently from the examples used during testing. Retrieval systems may therefore return text that is semantically adjacent but factually incorrect.   Vector Collisions Embedding space frequently contains multiple chunks that appear equally similar to the query. When chunk size is small or language is generic, retrieval results become unstable and inconsistent.   Data Freshness Debt Enterprise data sources change constantly. If document indexes are refreshed weekly—or not at all—the system may confidently answer questions using outdated information. The core issue is that retrieval is often under-specified.   Many RAG pipelines still rely on a single vector search call with a default top_k value, without measuring: – retrieval correctness – coverage or freshness. Figure 1 — Production RAG pipelines are retrieval-first systems The Three Pillars of Accuracy: Production RAG Architecture Reliable Production RAG architecture systems depend on three interacting components. Weakness in any single layer degrades the entire system. Pillar A — Data Quality Before tuning retrieval algorithms, teams must first address corpus quality. If the indexed knowledge base is poorly structured or lacks provenance metadata, retrieval tuning becomes an endless compensation exercise.   Chunking Strategy Chunking determines what the retriever can realistically discover.   Recommended practices include: – Prefer semantic chunking instead of fixed token boundaries when document structure matters. – Apply 10–20% overlap to preserve definitions and contextual constraints. – Ensure chunks remain answerable units containing a claim and supporting context. Pillar B — Retrieval Precision Pure vector search performs well for semantic similarity but struggles with: – exact identifiers – rare terminology – negation or constraint languages.   Cross-Encoder Reranking Initial retrievers typically rely on bi-encoders, which score queries and documents independently. This makes them fast but approximate. To improve precision, production pipelines apply cross-encoder re-rankers.   A common architecture: – Retrieve a large candidate set (top_k = 40–100) – Apply cross-encoder reranking – Select final context (top_k = 5–12) Pillar C — Generation Guardrails Even with accurate retrieval, generation models can still drift from the source material. Guardrails make system behaviour predictable.   Context Window Management – Cap total context tokens – Deduplicate similar chunks – Preserve document order for narrative coherence   Citation Requirements Models should reference: – chunk identifiers – document sources – timestamps when applicable.   Refusal Policies If retrieval confidence is low or context conflicts: “I do not have enough evidence to answer that question.” Figure 2 — RAG accuracy depends on data quality, retrieval precision and generation guardrails Enterprise RAG Technology Stack: Production RAG architecture Layer Basic RAG Enterprise RAG Ingestion Manual Uploads Structured ingestion pipelines Chunking Fixed tokens Semantic chunking with metadata Indexing Single vector index Hybrid lexical + vector indexes Retrieval Vector top_k search Query routing + hybrid merge Reranking None Cross-encoder reranking Enterprise-grade RAG requires observability and measurement, not just infrastructure. Evaluating Production RAG Architecture System Performance: Reliable deployment requires measurable improvements. Two core metrics dominate RAG evaluation.   Faithfulness Is the generated answer supported by retrieved context?   Relevance Was the retrieved evidence actually related to the query? Frameworks such as Production RAG Architecture and TruLens provide automated scoring for these metrics.   A practical evaluation workflow includes: – Create a golden question set representing real user queries. – Track retrieval metrics such as recall@k and rerank lift. – Measure generation faithfulness and answer relevance. – Run regression tests after each index update or prompt modification.   A key engineering principle emerges: Retrieval must be optimized before generation. Figure 3 — Cost and latency trade-offs across model classes Conclusion: Production Deployment Checklist Teams preparing for enterprise Production RAG architecture deployment should validate the following: – Define an accuracy contract specifying citation requirements and refusal conditions. – Implement semantic chunking with overlap and comprehensive metadata. – Deploy hybrid retrieval combining BM25 and dense embeddings. – Add cross-encoder reranking to refine the final context set. – Enforce context window management and chunk deduplication. – Instrument end-to-end tracing from query to generation. – Establish an evaluation harness using RAGAS or TruLens. – Budget latency and operating cost through model tiering and caching. – Automate index freshness using scheduled and event-driven updates.   Production RAG architecture systems succeed not because of larger language models, but because of disciplined retrieval engineering and continuous evaluation.   👉 The best time to start was yesterday. The second-best time is today-with Logassa Inc and our advanced AI solutions. Know more about our works with our Blogs. Happy Reading!

Production RAG Architecture: Moving Beyond Prototypes Read More »

Clinical-grade RAG architecture for healthcare decision support

Clinical-Grade RAG Architecture for Healthcare

Architecting Trust: Why Clinical-Grade RAG Architecture Fails in Clinical Environments? ⏱ 8–9 min read | 🏥 Healthcare AI & Clinical Innovation | 🎯 For Healthcare Leaders, Clinical Decision Makers & Professionals Executive Summary: Clinical-Grade RAG Architecture Clinical-Grade RAG Architecture or Generic “vector DB + LLM” Retrieval-Augmented Generation (RAG) patterns are not clinically trustworthy because they optimize for plausible language – not verifiable medical evidence. In healthcare environments, architecture must enforce: – Medical Entity Linking (UMLS-aware normalization) – Attribution-first generation with zero-tolerance hallucination policy (AQA) – Privacy-preserving, PHI-scoped retrieval – Temporal reasoning and time-weighted ranking The objective is not automation of diagnosis. The objective is Clinical Decision Support (CDS) for Clinical-Grade RAG Architecture that is evidence-grounded and auditable. The Clinical Challenge: Clinical-Grade RAG Architecture Clinical-Grade RAG Architecture documentation is heterogeneous and longitudinal. A single patient record may include: – Structured billing codes (ICD-10, CPT) – Problem lists – Radiology narratives – Discharge summaries – Medication reconciliations – Scanned PDFs Even within one EHR, semantic consistency is not guaranteed. Generic RAG fails due to: – Synonymy: “myocardial infarction” vs “heart attack” – Abbreviation overload: “MS” (multiple sclerosis vs morphine sulfate) – Negation complexity: “no evidence of pneumonia” – Temporal drift: 2018 medication list vs 2024 reconciliation In a consumer chatbot, hallucination is inconvenient. In healthcare, it is a patient safety risk. Therefore, Clinical-Grade RAG Architecture must be engineered as a CDS capability – supporting clinicians with evidence while preserving licensed medical accountability. Figure 1. Clinical-grade RAG pipeline: MEL → temporal retrieval → attribution → verification → HITL Technical Architecture (Risk-Averse by Design) This architecture is intentionally conservative. It is designed to support clinicians – not replace them Pillar A Medical Entity Linking (MEL) with Unified Medical Language System (UMLS) Problem: Standard embeddings underperform in biomedical synonymy and abbreviation ambiguity. Clinical-Grade Approach – Extract problems, medications, labs – Map mentions to UMLS CUIs – Preserve original surface forms for auditability Query normalization enables: – Expansion (“heart attack” → myocardial infarction, MI) – Constraint preservation (negation, temporality) Result: Retrieval precision improves without sacrificing traceability. The system remains CDS. Clinicians verify the cited source. Pillar B Hallucination Zero-Tolerance via Attributed Question Answering (AQA) Healthcare cannot tolerate plausible guesses. AQA reframes generation as attribution: The model may state a clinical fact only if it can cite a supporting span. Implementation Pattern – Retrieve candidate evidence – Generate answer with explicit citations – Verify claim-level support against spans Target metric: – Increased claim support rate – Controlled reduction in answer rate In medicine, abstention is often safer than over-answering. Pillar C PHI-Aware Retrieval & Localized Vector Stores Clinical text contains Protected Health Information (PHI). Architecture must enforce: – Patient-scoped retrieval Role-Based Access Control (RBAC) – Encrypted-at-rest indices – Tenant isolation – Audit logging For CDS workflows, de-identification is often insufficient. Access controls must be enforced pre-retrieval – not post-generation. Deployment may be on-prem or within private VPC environments aligned with HIPAA compliance standards. The system supports clinical workflows. Interpretation remains the responsibility of a licensed practitioner. Pillar D Temporal Context & Time-Weighted Retrieval Clinical truth evolves over time. Generic similarity search ignores recency. Clinical-grade retrieval introduces: – Timestamp decay functions – Encounter-based bucketing – Query-aware recency weighting Example: – “Current medications” → prioritize latest reconciliation – “History of diabetes” → include longitudinal evidence This ensures safer CDS behavior while preserving historical context. Figure 2. Safety-first pillars for Medical RAG Consumer RAG vs Clinical-Grade RAG Architecture Area Consumer RAG Medical RAG (Clinical-Grade) Security Cloud – First, Broad Indexing Patient – Scoped Retrieval, Private Vector Stores, RBAC, Audit Accuracy Similarity – Only Retrieval UMLS-Backed MEL + Hybrid Retrieval Time Often Ignored Time – Weighted Ranking Attribution Optional Citations Mandatory Claim – Level Verification Hallucination Mitigated Heuristically Zero – Tolerance + Abstention Policy Clinical trustworthiness increases with verification, even if latency & compute cost rise. The Truth-Check Flow: Clinical-Grade RAG Architecture Step 01 Retrieve & Constrain – Validate patient scope – Enforce access rights – Hybrid retrieval (lexical + biomedical embeddings) – Apply temporal weighting Output: Ranked evidence set with metadata. Step 02 Generate with Attribution – Every claim must cite source + timestamp – No diagnostic directives – Evidence presentation only Step 03 Verify & Decide – Claim-level span verification – Unsupported claims removed or downgraded – Route to HITL if ambiguity persists Output: Verified summary + audit bundle (citations, spans, confidence scores) Figure 3. Trust vs latency trade-off in clinical RAG systems Roadmap for HIPAA-Aligned Deployment: Clinical-Grade RAG Architecture Phase 0 Governance – Define CDS scope – Establish escalation pathways – Formalize change control Phase 1 Secure Ingestion – Normalize HL7 / FHIR / C-CDA – Preserve provenance – Attach metadata (patient, encounter, author, timestamp) Phase 2 Clinical-Grade Retrieval – Biomedical embeddings – UMLS-aware MEL – Hybrid + temporal ranking – Cross-encoder reranking for high-risk queries Phase 3 Attribution & Verification – AQA enforcement – Abstention policy – Persistent audit bundle Phase 4 Safety Monitoring – Track faithfulness – Monitor answer rate – Evaluate retrieval sensitivity – Clinical stakeholder review loops Phase 5 Deployment – Prefer on-prem or private VPC – Encryption in transit & at rest – Least-privilege IAM – Vendor risk management Conclusion: Clinical-Grade RAG Architecture Clinical-Grade RAG Architecture systems optimize for fluency. Clinical-Grade RAG Architecture systems optimize for verifiable truth, temporal correctness and patient safety. For CMIOs and healthcare data architects, the decision is architectural – not experimental. Trust in clinical AI is not a feature. It is the outcome of deliberate design. At Logassa, we engineer AI systems where reliability, compliance and auditability are foundational – not optional. 👉 The best time to start was yesterday. The second-best time is today-with Logassa Inc and our advanced AI solutions. Know more about our works with our Blogs. Happy Reading!

Clinical-Grade RAG Architecture for Healthcare Read More »

LLMs in healthcare assisting clinicians with AI-powered documentation

LLMs in Healthcare: Models & Use Case Guide

LLMs in Healthcare: Use Cases, Top Models & Safe Deployment ⏱ 12–15 min read | 🏥 Healthcare AI & Clinical Innovation | 🎯 For Healthcare Leaders, Clinical Decision Makers & Professionals Introduction: LLMs in Healthcare Large Language Models (LLMs in healthcare) are AI systems trained on massive text corpora to understand, summarize and generate human-like language. In clinical environments, they function as assistive copilots-helping clinicians, administrators and operations teams process complex medical information faster and more accurately. Healthcare data is highly unstructured and fragmented across systems: progress notes, discharge summaries, radiology reports, referral letters, prior authorizations and patient education materials. Consequently, LLMs in healthcare are most impactful where cognitive load is high and documentation is repetitive. However, LLMs can produce confident but incorrect outputs (hallucinations). Therefore, safe healthcare AI deployment requires structured governance, human validation, traceable audit logs and secure infrastructure design. At Logassa, we approach healthcare AI from a systems engineering perspective-ensuring scalability, interoperability and compliance across clinical workflows. How LLMs in Healthcare Are Used 1. Clinical Documentation Automation – Drafting SOAP notes, discharge summaries, referral letters and operative notes for LLMs in healthcare – Structuring free-text into standardized templates (problems, medications, allergies) – Reducing administrative burden when integrated with EHR systems 2. EHR Summarization & Chart Review – Condensing long patient histories into structured timelines – Identifying missing context such as pending labs or overdue screenings – Structuring free-text into standardized templates and chart reviews 3. Assistive Clinical Decision Support – Retrieving guideline snippets with citations for LLMs in healthcare – Generating differential diagnosis considerations and care pathway checklists – Assistive systems only – not autonomous decision-makers 4. Patient Communication & Education – Producing patient-friendly discharge instructions – Multilingual explanation generation – Guardrailed triage chat interfaces with escalation protocols 5. Medical Coding & Billing Support – Suggesting ICD and CPT codes from clinical documentation – Flagging incomplete notes for coding accuracy – Automating prior authorization drafts 6. Research & Pharmacovigilance – Literature summarization and biomedical evidence extraction – Clustering adverse event narratives – Summaries of data and creates analysis report Top Models of LLMs in healthcare Availability and licensing evolve rapidly. This is a technical comparison, not a vendor endorsement. 1. OpenAI – GPT-4 / GPT-4o Strengths: – High-quality reasoning and summarization – Workflow automation capabilities among LLMs in healthcare Limitations: – Not healthcare-specialized by default – Requires structured guardrails 2. Google – Gemini / MedLM Strengths: – Healthcare-focused variants – Integration with Google Cloud healthcare stack Limitations: – Enterprise-focused access – Governance required 3. Anthropic – Claude Strong long-context reasoning; useful for compliance and policy drafting with LLMs in healthcare. 4. Meta – Llama 3 Open-weights model family suitable for private cloud and on-prem healthcare copilots. 5. Mistral AI – Mistral Efficient multilingual deployment with smaller compute footprint. 6. Technology Innovation Institute – Falcon Open-weights models are often selected for sovereign or local data hosting needs. 7. Google Research – Med-PaLM 2 Medical research-focused reasoning model (limited public access). 8. Microsoft Research – BioGPT Optimized for biomedical literature generation and extraction. 9. ClinicalBERT (Clinical NLP Family) Designed for structured extraction from EHR notes and classification tasks. 10. Medical ASR + LLM Speech-to-text systems paired with LLM structuring layers for automated clinical documentation for LLMs in healthcare. Comparative Overview of LLMs in Healthcare Applications Model/ Family Medical Specific Open Weights Typical Use Case GPT-4 / GPT-4o No No Documentation, AI Assistants Gemini / MedLM Partial No EHR WorkFlows Claude No No Compliance & Long Docs Llama 3 No Yes Custom Healthcare Co-Pilots Mistral No Some Multilingual Assistants Falcon No Yes On-Prem Deployment Med-PaLM 2 Yes No Medical Q&A Research BioGPT Yes Yes Biomedical Research ClinicalBERT Yes Yes EHR Extraction Medical ASR + LLM Work-Flow Based Varies Speech-To-Notes Safety, Governance & Compliance: LLMs in healthcare Safe deployment of LLMs in healthcare requires: – Human-in-the-loop review – Confidence thresholds and refusal mechanisms – Audit logs and traceability – Secure infrastructure (HIPAA / regional compliance) – Clinical validation and model evaluation LLMs in healthcare should assist decision-making – not replace licensed medical professionals. Conclusion: LLMs in Healthcare LLMs in healthcare are reshaping documentation, analytics, patient communication and clinical workflow automation. However, real value emerges only when systems are engineered with compliance, interoperability and validation in mind. We focus on production-ready AI architecture-designed for reliability, scalability and safe clinical integration. 👉 The best time to start was yesterday. The second-best time is today-with Logassa Inc and our advanced AI solutions. Know more about our works with our Blogs. Happy Reading!

LLMs in Healthcare: Models & Use Case Guide Read More »

NVIDIA Parakeet v2 vs OpenAI Whisper ASR Model Comparison

ASR Model Comparison: NVIDIA Parakeet V2 vs OpenAI Whisper

NVIDIA Parakeet v2 vs OpenAI Whisper: Top ASR Model Comparison ⏱ 12 min read | 🤖 AI Automation | 🎯 For Decision Makers & Leaders Introduction: ASR model comparison Automatic Speech Recognition (ASR) systems have evolved from simple transcription tools into mission-critical enterprise infrastructure. From call centers and media transcription to analytics, assistants, and multilingual applications, ASR model selection directly impacts cost, latency, and scalability. This ASR model comparison evaluates NVIDIA Parakeet v2 and OpenAI Whisper, two widely adopted speech recognition models, across architecture, benchmarks, latency, throughput, deployment, licensing, and real-world production trade-offs. At Logassa LLC, we analyze ASR models through a deployment-first lens, focusing on operational efficiency, system scalability, and long-term enterprise viability. Architecture Overview: ASR model comparison NVIDIA Parakeet v2 Parakeet v2 is built on a FastConformer encoder paired with a Token Duration Transducer (TDT) decoder. This architecture enables: – Extremely high GPU throughput – Low-latency decoding – Native word-level timestamps By explicitly predicting token durations, the TDT decoder ensures stable alignment, making Parakeet highly reliable for subtitles, analytics, and time-sensitive. OpenAI Whisper Whisper uses a Transformer encoder–decoder architecture, trained end-to-end on massive multilingual datasets. Key strengths include: – Strong generalization – Multilingual speech recognition – Built-in translation capabilities However, Whisper relies on autoregressive decoding, which introduces higher latency and lower throughput in enterprise-scale ASR model comparison scenarios Training Data & Language Support Parakeet v2 is English-only, trained on curated, high-quality speech datasets optimized for accuracy and inference speed. Whisper is trained on approximately 680,000 hours of multilingual audio, supporting around 99 languages, including both transcription and translation.   Strategic trade-off: Parakeet emphasizes performance efficiency, while Whisper prioritizes language coverage and robustness. Performance Characteristics Throughput & Latency Parakeet v2 achieves extremely high GPU throughput, reaching ~3380× real-time factor (RTFx) in batch transcription workloads. Whisper Large-v3 delivers significantly lower throughput (~200× RTFx) due to its larger model size and autoregressive decoding pipeline.   Accuracy – Parakeet v2 (clean audio): ~6.0% WER – Whisper Large-v3 (clean audio): ~8.4% WER Whisper generally performs better in noisy and multilingual environments, while Parakeet excels in clean, high-volume English workloads. Deployment & Integration Parakeet v2 – Optimized for NVIDIA GPU infrastructure – Integrated with NVIDIA Riva – Accelerated using TensorRT – Ideal for large-scale, production-grade ASR pipelines Whisper – Deployable locally or via OpenAI APIs – ONNX and quantized variants available – Suitable for rapid experimentation and flexible deployment Parakeet v2 vs Whisper: ASR Model Comparison Metric NVIDIA Parakeet v2 OpenAI Whisper Large-v3 Parameters 600M 1.55B Architecture FastConformer + TDT Transformer Encoder – Decoder Training Data ~0.5K Hrs – English 680K Hrs – Multilingual Languages English Only ~99 Languages Punctuation Native Native WER (clean) ~6.0% ~8.4% WER (noisy) 8.4%@5dB Robust GPU Throughput ~3380X ~200X GPU Memory 4–8 GB 4–8 GB License CC-BY-4.0 Apache-2.0 Commercial Use Yes Yes Decoding Strategy & Timestamp Accuracy: ASR model comparison Parakeet’s Token Duration Transducer explicitly models how long each word lasts, producing reliable word-level timestamps. Whisper infers timestamps indirectly from token positions, which is sufficient for phrase-level alignment but may drift in long or noisy recordings. Impact: – Subtitles & captions → Parakeet preferred – Analytics & diarization → Parakeet preferred – General transcription → Both acceptable Latency VS Throughput Trade-Off Parakeet v2 excels in batch transcription, making it suitable for: – Call centers – Media archives – Large-scale analytics Whisper’s higher per-request latency becomes more noticeable in real-time or high-volume enterprise environments. Hallucinations & Failure Modes: ASR model comparison Whisper is known to hallucinate text during silence due to continuous token prediction. Parakeet, when paired with Voice Activity Detection (VAD), avoids generating output during non-speech segments. Mitigation strategies: – Apply VAD – Drop low-confidence tokens – Enforce confidence thresholds Use Case Recommendations for ASR Model Comparison Scenario Recommended Model Reason High – Volume English Transcription Parakeet v2 Cost + Throughput Multilingual Applications Whisper Language Coverage Real – Time Assistants Parakeet (RNNT) Low Latency Research & Experimentation Whisper Flexibility Subtitle Alignment Parakeet Word Timestamps Noisy Field Recordings Whisper Robust Training When NOT to Use PARAKEET v2 ❌ – Multilingual requirements – CPU-only infrastructure – Speech translation use cases When NOT to Use Whisper ❌ – Massive English-only workloads – Strict low-latency systems – GPU cost-sensitive pipelines Production Architecture Comparison Parakeet Pipeline Audio → VAD → GPU Batch → FastConformer → TDT → Transcript + Word Timestamps Whisper Pipeline Audio → Pre-Processing → Encoder → Autoregressive Decoder → Transcript Core Difference: – Parakeet optimizes inference efficiency. – Whisper optimizes representational generalization. Conclusion: ASR model comparison Parakeet v2 is an engineering-optimized ASR system built for speed, scale, and precision in English transcription. Whisper is a research-driven, multilingual ASR model, optimized for robustness and global language support. At Logassa LLC, we help enterprises choose ASR architectures based on production constraints, cost models, and long-term scalability, not just benchmark scores.   👉 The best time to start was yesterday. The second-best time is today-with Logassa Inc and our advanced AI solutions.

ASR Model Comparison: NVIDIA Parakeet V2 vs OpenAI Whisper Read More »

Pipeline integrity evidence-pack agent dashboard

Pipeline Integrity Evidence-Pack Agent

Pipeline Integrity Evidence-Pack Agent: The Next Big Indus ⏱ 10 min read | 🤖 AI & Automation | 🎯 For Decision Makers & Leaders Introduction: Pipeline Integrity Evidence-Pack Agent Pipeline Integrity Evidence-Pack Agent teams already do the hardest part: identifying threats, assessing anomalies, executing digs and closing repairs. The real bottleneck is proving the work. At Logassa Inc, we build Pipeline Integrity Evidence-Pack Agents that transform fragmented integrity artifacts-In-Line Inspection (ILI) results, dig records, photos, work orders and repairs-into one traceable, citation-backed, audit-ready evidence pack per anomaly. The result: less rework, faster audits and stronger regulatory confidence-without removing human engineering authority. The Core Problem: Integrity Data Is Everywhere, Proof Is Not Pipeline operators are required to run integrity programs that identify threats, assess pipelines (often using In-Line Inspection (ILI)), validate results, execute repairs and document outcomes. In the U.S., this falls under integrity management requirements overseen by PHMSA. Too Many Artifacts A single ILI run can generate: – Vendor reports (PDFs + tables) – GIS locations and mileposts – Dig sheets with measurements and properly acquired photos – Work orders & repair close notes Linking Is Manual Teams must manually connect: ILI anomaly → dig → verification → repair → close-out – IDs rarely match across systems – Photos and notes are unstructured – Evidence packs take days to assemble Audits Demand the Full Story Auditors ask “show me how you got there.” That requires: – data → decision → action → approval – Clear narrative with attachments – Repeatability The Manual Reality (and Why It Doesn’t Scale) Most integrity teams rely on spreadsheets, shared drives, emails and templates. The process works-but people become the integration layer. Where time is lost – Downloading and reformatting ILI data – Reconciling mismatched IDs and locations – Copying narratives into templates – Chasing missing photos or sign-offs The Result – Inconsistent evidence packs – Higher audit risk – Slower response to regulator questions – Knowledge locked in individuals The Solution: A Pipeline Integrity Evidence-Pack Agent Think of the agent as a pipeline integrity analyst assistant. It reads, links, validates and assembles evidence-but never replaces engineering judgment. What the AI Agent Does (and Does Not Do) ✅ What the Pipeline Integrity Evidence-Pack Agent Does – Ingests ILI reports, dig packages, photos, work orders and repairs – Links records by anomaly ID, location, asset context and time – Generates a structured evidence pack. – Gap-checks missing proof (photos, measurements, sign-offs) – Summarizes decisions with citations to approved procedure ❌ Pipeline Integrity Evidence-Pack Agent Donts – Approve repairs or override engineers – Invent measurements or infer missing data – Cite unapproved documents – Hide uncertainty or low-confidence matches Rule: No citation → no claim. 0 % less time spent assembling packs (pilot target; measure baseline vs after) 0 % fewer missing-attachment findings (goal via automated gap-checking) 0 % traceability per anomaly (every claim tied to a record or source) Real-World Implementation Flow: Pipeline Integrity Evidence-Pack Agent ILI Run Arrives Vendor delivers ILI report and anomaly list (PDF/CSV). Single Source of Truth Created Agent normalizes IDs, aligns GIS locations and creates one anomaly record per issue. Digs Are Linked Dig notes, measurements and photos are matched with confidence scoring. Repairs & Close-Out Attached Work orders, repair methods, post-repair checks and approvals are pulled in. Evidence Pack Generated (Draft) Includes: Narrative summary Anomaly table “What we did and why” Attachment checklist Human Review & Approval (Mandatory) Engineers validate, edit if needed and approve final packs. What a Complete Evidence Pack Includes?: Pipeline Integrity Evidence-Pack Agent – ILI run context and definitions – Anomaly prioritization rationale – Dig verification data + photos – Repair actions and work order references – Validation, close-out summary and signatures Common Gaps the Agent Flags Automatically: Pipeline Integrity Evidence-Pack Agent – Location mismatches (ILI vs dig GPS/milepost) – Missing photo evidence – Incomplete measurements – Missing repair close-out sign-offs – Unclear deferment rationale Implementation Blueprint (Agentic AI Pattern): Pipeline Integrity Evidence-Pack Agent Data Inputs – ILI reports and anomaly tables – GIS pipeline routes – Dig packages (notes, photos, measurements) – CMMS work orders – Internal procedures and standards Agent Steps – Normalize IDs, locations, timestamps – Match anomalies to digs with confidence scoring – Retrieve policies for citations (RAG) – Validate completeness via rules engine – Generate draft evidence pack + gap list – Route to engineer for approval Reference Technology Stack (Typical) Data & Systems – RAG with vector database – Agent workflow orchestrator – Document parsing (PDFs, images, metadata) – Rules engine for completeness validation AI Layer – RAG with vector database – Agent workflow orchestrator – Document parsing (PDFs, images, metadata) – Rules engine for completeness validation Outputs – Word/PDF evidence packs – Attachment bundles – Immutable audit logs and approvals – Status dashboards Pilot Metrics That Matter Operational – Time to assemble evidence pack – Rework rate due to missing items – Time from ILI receipt → review-ready pack Quality – Attachment completeness score – Traceability score – Mismatch detection rate – Audit response time Final Thought: Pipeline Integrity Evidence-Pack Agent Pipeline Integrity Evidence-Pack Agent programs don’t fail due to lack of effort-they fail when proof is fragmented. At Logassa Inc, our Pipeline Integrity Evidence-Pack Agents remove the paperwork burden while strengthening traceability, audit readiness and regulatory confidence-without compromising engineering authority. 👉 The best time to start was yesterday. The second-best time is today-with Logassa Inc and our advanced AI solutions. Know more about our works with our Blogs. Happy Reading! US Sources: Pipeline Integrity Evidence-Pack Agent These are reputable US-focused references you can cite in the blog and sales conversations for Pipeline Integrity Evidence-Pack Agent: PHMSA integrity management resources – PHMSA: Gas Transmission Integrity Management – PHMSA: Integrity Management overview US regulations (definitions & rule) – 49 CFR Part 192 (eCFR) – 49 CFR Part 192 Subpart O – Federal Register (2022): Gas Transmission rulemaking Standards / industry references – ASME B31.8S – API Recommended Practice 1160 (fact sheet PDF) Extra (assessment context) – PHMSA Gas Transmission

Pipeline Integrity Evidence-Pack Agent Read More »

Drilling NPT prevention agent monitoring real-time operations

Drilling NPT Prevention Agent

Drilling NPT Prevention Agent: Stop Losing Days to Surprises ⏱ 10 min read | 🤖 AI & Automation | 🎯 For Decision Makers & Leaders Introduction: Drilling NPT Prevention Agent Drilling NPT Prevention Agent (NPT) remains one of the most persistent and expensive challenges in drilling operations. Despite experienced crews, advanced rigs and standardized reporting, unexpected events still cost operators days of lost time per well. At Logassa Inc, we design Drilling NPT Prevention Agent that continuously monitor real-time drilling signals, analyze Daily Drilling Reports (DDRs), retrieve lessons from offset wells and generate action-ready, evidence-backed alerts-while ensuring all operational decisions remain fully human. The Problem: Why Drilling Teams Still Lose Time Drilling NPT Prevention Agent (NPT) refers to any time spent on drilling activities that do not advance the well. Common causes include: – Equipment dysfunction – Wellbore instability (e.g., stuck pipe) – Waiting on decisions – Operational rework Most rigs already capture NPT categories using IADC DDR Codes and real-time data is streamed through standards such as WITSML.Yet incidents still escalate. Why NPT Happens – Even With Experienced Teams: Drilling NPT Prevention Agent NPT is rarely caused by negligence. It emerges from human limits under complex conditions: – High-volume real-time signals are easy to miss during busy shifts – Context is fragmented across sensors, DDR narratives and historical wells – Shift handovers lose the “story” behind subtle trend changes – Teams react after thresholds are crossed instead of earlier trend shifts 💡Bottom line: The rig already produces enough data to prevent many issues. The challenge is converting that data into fast, consistent, evidence-based decisions. What “Early Warning” Actually Means in Drilling: Drilling NPT Prevention Agent True early warning is not another alarm. It means: – Detecting trend deviations, not just threshold breaches – Explaining “why this matters now” in plain language – Attaching verifiable evidence (signals, time windows, notes) – Suggesting mitigations aligned to approved practices If there is no evidence, there should be no alert. The Manual Reality Today (and Why It’s Costly) Most Drilling NPT Prevention Agent teams rely on dashboards, shift calls and expert judgment. This approach works but no scale. What Teams Do Manually? – Monitor multiple real-time dashboards – Write and interpret DDR narratives – Search offset wells for similar symptoms – Coordinate calls between rig, engineers and RTOC – Decide under pressure, document later Why this Consumes Time & Resources? – Constant context switching between tools – Tribal knowledge locked in experts or PDFs – Slow retrieval of similar cases during incidents – Inconsistent decisions across shifts – Weak feedback loops into future planning 💡Result:Late escalation, repeated issues across wells and growing coordination overhead-especially in remote monitoring environments. The Solution: Drilling NPT Prevention Agent A Drilling NPT Prevention Agent acts as an always-on co-pilot. It does not control equipment. It does not replace engineers. It supports faster, more consistent decision-making. How Agentic AI + GenAI Solve the Problem Detect Identifies early risk patterns from trends-not just alarms-and assigns severity and confidence. Evidence Attaches exact data windows, charts and DDR excerpts. No evidence → no claim. Retrieve Uses Retrieval-Augmented Generation (RAG) to pull learnings from offset wells, SOPs and approved runbooks. Explain Summarizes why this matters now in clear, operational language. The engineer stays in control. Suggest Proposes mitigations aligned to site-approved practices. Escalate Routes alerts to the right roles and logs outcomes to strengthen future recommendations. Full audit trail included. What Makes This “Agentic” (Not a Chatbot) The agent executes a multi-step workflow:   Detect → Retrieve → Explain → Suggest → Escalate → Log This is orchestration across systems-not conversational guessing. Real-World Deployment Flow Ingest live Drilling NPT Prevention Agent parameters, DDR notes and offset well documents Detect early risk patterns and assign confidence Retrieve similar cases and proven mitigations Generate evidence-backed alerts with “why now”   Human review → decision → outcome logged What a High-Quality Alert Includes? Risk type: e.g., developing stuck pipe Evidence: torque trend, pressure change, ROP drop Context: hole section, BHA, mud properties Suggested actions: aligned to approved runbooks Escalation: Drilling NPT Prevention Agent engineer, superintendent if risk increases Reference Architecture (High Level) Data & Integration Layer – WITSML ingestion and normalization – Time-series stores (rig sensors, mud logging, MWD/LWD) – Document repositories (DDRs, post-well reports) – Well master data (rig, section, BHA metadata) AI & Orchestration Layer – Anomaly detection and risk classification – RAG grounded in approved documents – Agent orchestration with guardrails – Confidence scoring, explainability, audit logs Pilot Scorecard: How Success Is Measured Operational Metrics – Time-to-detect – Time-to-decision – Engineer-validated NPT hours avoided – Reduction in repeated issues Quality Metrics – Engineer usefulness rating per alert – % alerts with evidence and explanation – False alarm rate – Recall on known precursor patterns Safety & Governance Guardrails (Non-Negotiable) Human-in-the-loop approvals Role-based access control (RBAC) “No evidence → no claim” policy End-to-end audit logging Why Does This Improves Safety? Earlier awareness reduces emergency conditions Consistency across shifts improves handovers Evidence-backed alerts reduce decision pressure Stronger learning loops improve future wells Final Thought: Drilling NPT Prevention Agent Drilling NPT Prevention Agent are not about automating drilling decisions.They are about supporting the people who make them-earlier, more consistently and with better evidence. At Logassa Inc, we build agentic AI systems that respect operational authority while delivering measurable reductions in downtime, risk and uncertainty.   👉 The best time to start was yesterday. The second-best time is today-with Logassa Inc and our advanced AI solutions. Know more about our works with our Blogs. Happy Reading!

Drilling NPT Prevention Agent Read More »

AI-driven inventory management system dashboard

AI-Driven Inventory Management System

AI-Driven Inventory Management System Using n8n Automation ⏱ 10 min read | 🤖 AI & Automation | 🎯 For Decision Makers & Leaders Inventory Is No Longer a Storage Problem: AI-Driven Inventory Management System For modern enterprises, the AI-Driven Inventory Management System has evolved far beyond tracking stock levels. Today, it is about anticipating demand, optimizing capital and making intelligent decisions before disruptions occur.   However, many organizations still: – React too late to demand shifts, chasing outdated trends – Rely on manual forecasting methods that lack predictive accuracy – Use ERP systems that report historical data instead of future insights As a result, inventory becomes a liability instead of a strategic asset. The Critical Gap in Traditional Inventory & ERP Systems: AI-Driven Inventory Management System Even advanced ERP platforms are fundamentally descriptive, not predictive. They provide visibility into current inventory but fail to answer what truly matters: what’s coming next.   This limitation leads to: – Excess capital tied up in overstock, restricting cash flow – Emergency procurement cycles, eroding margins – Lost revenue opportunities due to stockouts and delays To compete at scale, businesses need inventory systems that think ahead. Our Solution: An AI-Driven Inventory Management System At Logassa Inc, we designed an AI-Driven Inventory Management System that converts inventory data into real-time predictive intelligence. By orchestrating workflows through n8n automation and applying OpenAI-powered forecasting models, the system continuously analyzes trends, predicts demand and automates inventory decisions-while keeping ERP systems synchronized in real time. Why We Use n8n: Intelligent Orchestration at Enterprise Scale n8n is the backbone of our automation layer because it enables: – Seamless integration with ERPs, databases, APIs and data warehouses – Custom logic design without hard vendor dependencies – Enterprise-grade scalability without operational bottlenecks This architecture ensures flexibility, transparency and long-term scalability. 1. Continuous Data Ingestion Inventory levels, historical sales data and demand signals are collected automatically across systems. 2. AI-Powered Demand Forecasting OpenAI analyzes sales velocity, seasonality and trend patterns to generate forward-looking demand insights. 3. Decision Intelligence Layer n8n logic evaluates reorder points, overstock risks and optimal procurement quantities. 4. Automated Execution The system updates ERP records, generates purchase orders and sends alerts-all in real time. This ensures decisions are made before issues arise, not after they impact operations. Measurable Business Impact: AI-Driven Inventory Management System Organizations deploying this AI-driven inventory management system achieve: – Reduced stockouts and backorders – Optimized inventory holding costs – Faster, data-driven decisions – Improved cash flow visibility – Elimination of manual errors – Predictive planning capability – Audit-ready decision logs – Scalability without increasing headcount Industries We Support: AI-Driven Inventory Management System This solution is designed for complex, regulated and high-volume environments, including: Retail & E-commerce Manufacturing & Healthcare Logistics & Supply Chain FMCG Wholesale & Distribution Pharmaceuticals & Medical Supply The system adapts to SKU complexity, lead times, compliance rules and demand volatility. Deployment options include cloud or self-hosted, with no vendor lock-in. Live Demo: AI-Generated Purchase Order in Production – AI-Driven Inventory Management System The image below represents an AI-Driven Inventory Management System output, not a mock-up. The AI-driven workflow: – Identified a future stockout – Forecasted upcoming demand – Calculated reorder quantities – Automatically generated a purchase order – Sent notification emails without human intervention This is production-ready decision automation. Final Takeaway: AI-Driven Inventory Management System Inventory excellence today requires predictive intelligence, not reactive reporting. With an AI-Driven Inventory Management System, enterprises transform inventory from an operational burden into a competitive advantage. At Logassa Inc, we help organizations achieve this through AI-powered automation built for scale, compliance and long-term growth. 👉 The best time to start was yesterday. The second-best time is today-with Logassa Inc and our advanced AI solutions. Know more about our works with our Blogs. Happy Reading!

AI-Driven Inventory Management System Read More »